In 2025, Zero Trust and observability are converging to improve monitoring of distributed systems. Tracing must incorporate contextual, automated and verifiable access policies. OpenTelemetry, service-mesh proxies and authorisation engines such as OPA underpin this approach. A multi-cloud payment platform illustrates its measurable benefits and operational constraints.
Introduction – A crisis of trust in distributed systems
Micro-services architectures, edge computing, and the massive adoption of multicloud have multiplied the interaction points between services. Every network call potentially becomes an attack vector, while visibility into these flows remains fragmented. Recent incidents (e.g., the 2024 supply chain compromise) illustrate the gap between detection and prevention: ops teams detect anomalies too late, whereas access to the traces themselves is often limited to a small group of engineers.
The Zero-Trust (ZT) model, formalised by NIST SP 800-207 [1], proposes that implicit trust should never be granted, even within the network perimeter. Applied to observability, this principle implies that every trace request must be subject to dynamic authorisation, based on the requester's identity, the execution context, and the sensitivity of the observed data.
In 2025, organisations integrating distributed tracing with Zero-Trust access controls gain in:
- detection speed (immediate triggering of alerts as soon as an unauthorised request appears);
- regulatory compliance (auditability of access to monitoring data, GDPR and NIS2 requirements);
- operational resilience (limiting exposure in the event of a compromise of an observability component).
A Zero-Trust observability design must account for its technical foundations, implementation steps and organisational implications.
1. Context – Why Zero-Trust is becoming indispensable for observability
1.1 The evolution of threats
Lateral movement attacks exploit implicit trust between internal services. According to the ENISA report on Zero-Trust (2022) [2], more than 60% of recent incidents take advantage of insufficient visibility into inter-service flows.
1.2 Limitations of traditional observability approaches
Traditional solutions (e.g., aggregation of logs, metrics, and traces via a central server) often rely on:
- Static authentication (certificates or long-lived tokens).
- Coarse-grained access controls (global 'observer' role, lacking granularity).
These practices fail to restrict access to traces containing sensitive data (identifiers, personal information) and complicate compliance with access traceability requirements.
1.3 Zero Trust as a unifying framework
Zero Trust is built around three pillars:
| Pillar | Implication for observability |
|---|---|
| Strong identity | Each component (service, agent, tool) possesses a verifiable cryptographic identity (SPIFFE/SPIRE). |
| Least privilege access | Authorization policies are evaluated for every trace request. |
| Continuous verification | Context (geolocation, trust level, pod status) influences the access decision. |
Integrating these pillars into the tracing pipeline creates Zero-Trust observability, where monitoring data is itself protected.
2. Distributed Tracing – Fundamentals and Current Limitations
2.1 Tracing Principles
Tracing involves propagating a trace-id (and potentially span-ids) along a call chain to reconstruct the execution graph of a request. The dominant standards are:
- OpenTelemetry – a common specification for trace collection, instrumentation, and export [3].
- Jaeger, Tempo – storage and query back-ends.
2.2 Security Weaknesses
| Issue | Consequence |
|---|---|
| Unauthenticated context propagation (e.g., trace-id injection) | Possibility of falsifying observed flows. |
| Centralised storage without granular encryption | Risk of sensitive data exposure in the event of a breach. |
| Read/write access limited to a small group of engineers | Lack of audit traceability and non-compliance with 'who accessed what' requirements. |
These gaps justify the addition of dynamic access control at the collector or proxy level that intercepts trace requests.
3. Zero Trust principles applied to observability
3.1 Identity of trace emitters
The model recommends using the SPIFFE ID (Secure Production Identity Framework for Everyone) for each pod or serverless function [4]. The identifier is signed by a SPIRE authority server, guaranteeing its authenticity without relying on an internal PKI.
3.2 Context-based access policies
Authorization engines such as OPA (Open Policy Agent) allow rules to be defined in Rego:
package observability.allow

default allow = false

allow {
    input.service == "payment‑gateway"
    input.trace.sensitivity < 2          # niveau de sensibilité du span
    input.requester.identity = input.service   # même service que le producteur
}
These rules are evaluated at each call to the collector, taking into account:
- the sensitivity level of the trace (determined by metadata – e.g., personal data, secrets).
- of the execution context (geographic zone, pod status, TLS 1.3 compliance).
3.3 Immutable Audits and Logging
Every authorisation decision must be recorded in an immutable log, ideally signed via a blockchain or a tamper-evident logging service (e.g., AWS CloudTrail, Azure Monitor with immutable storage). This meets the traceability requirements of GDPR Art. 30 and NIS2.
4. Integrated Architecture – Tracing + Dynamic Access Controls
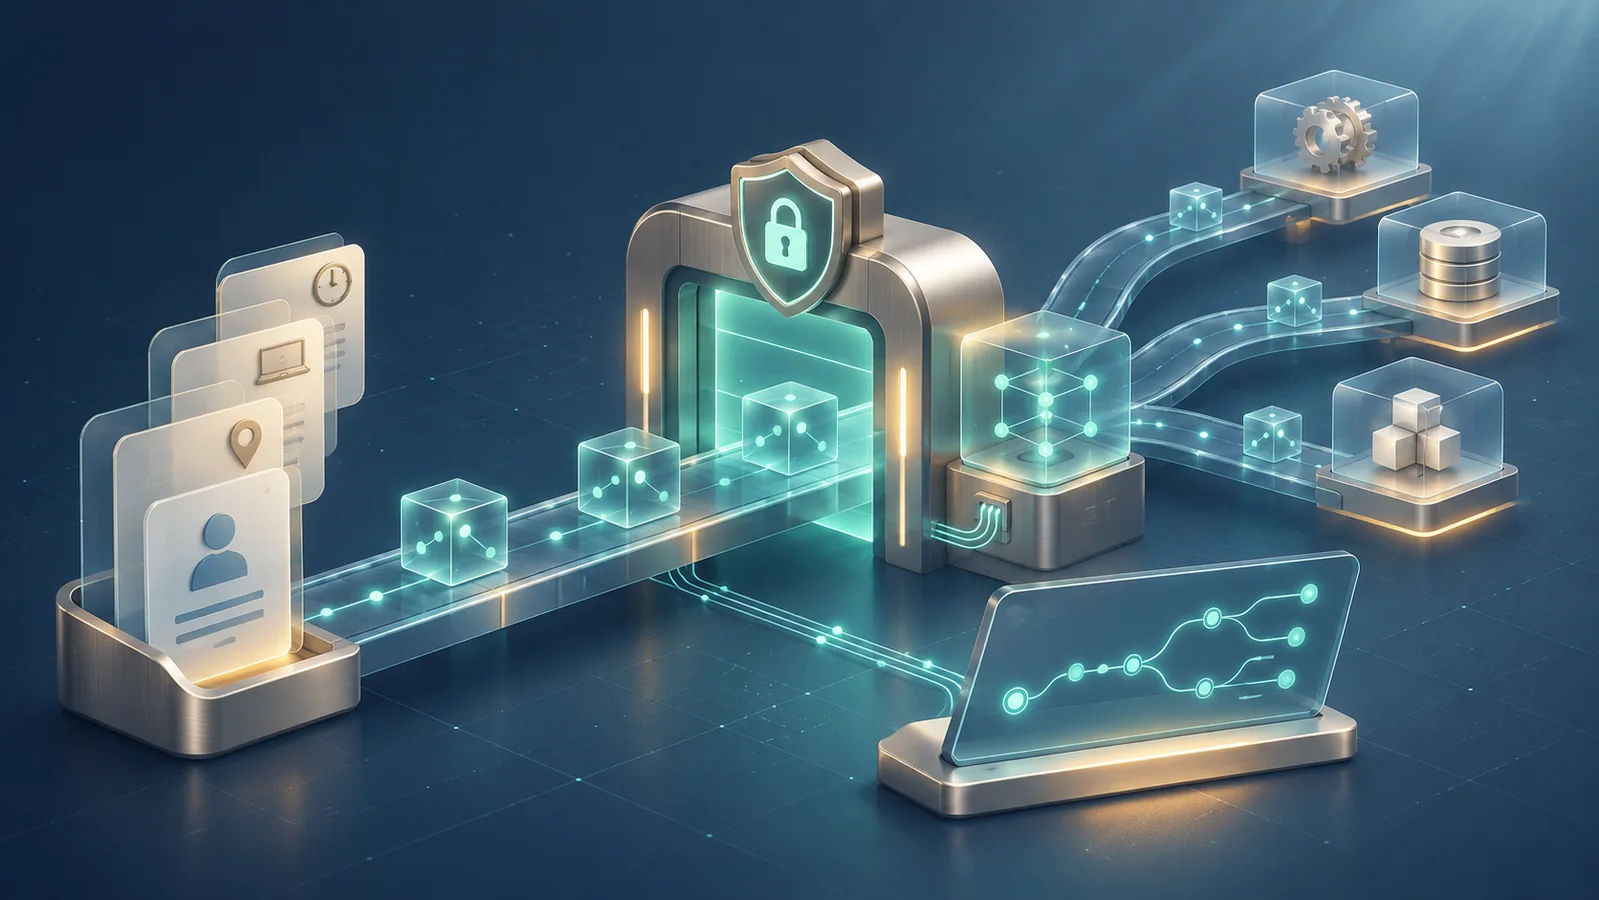
Box: Example Zero-Trust architecture for observability
!Simplified diagram (illustration not provided)
4.1 Key Components
| Component | Role in the trace flow |
|---|---|
| OpenTelemetry Agent (sidecar) | Instruments the application, injects the SPIFFE ID and sensitivity metadata. |
| Service-mesh proxy (Envoy/Istio) | Intercepts HTTP/gRPC requests to the collector, applies mutual TLS, and forwards identity attributes to OPA. |
| OPA Policy Engine | Evaluates Zero-Trust policies in real time; returns allow or deny. |
| Collector (OTel Collector) | Aggregates authorised traces, encrypts data at rest (AES-256), and sends them to the back-ends (Jaeger/Tempo). |
| Storage Backend | Stores spans in a compatible store (e.g., Cassandra, ClickHouse) with encryption at rest and granular RBAC access control. |
| Audit Log Service | Logs every OPA decision with timestamp, requester identity, and result. |
4.2 Processing Flow
- Instrumentation – The application creates a span; the OpenTelemetry agent adds the SPIFFE ID (spiffe://cluster/ns/pod).
- Propagation – The trace-id propagates via HTTP/gRPC headers (e.g., traceparent, tracestate).
- Interception – The service-mesh proxy receives the trace request, extracts the identity and metadata, then calls OPA.
- Evaluation – OPA applies contextual rules; if allowed, the proxy forwards the trace to the collector. Otherwise, it returns a 403 error and logs the incident.
- Storage & Audit – The collector encrypts the span and persists it; simultaneously, the access decision is recorded in the Audit Log Service.
This chain ensures that every piece of monitoring data benefits from the same level of access control as business data.
5. Technical Implementation – Standards, tools and best practices
5.1 Standardisation with OpenTelemetry
- Instrumentation: Use official SDKs (Java, Go, Python) version ≥ 1.8 to leverage native support for security attributes (attributes["security.identity"]).
- Exporter: Configure the otlp exporter using mutual TLS towards the collector.
5.2 Identity Management – SPIFFE/SPIRE
Deploy a SPIRE server in each cluster (on-prem or cloud). The daemon agent automatically assigns identities to workloads via runtime-based attestation (Kubernetes, Nomad).
- Reference: CNCF SPIFFE Specification v1.2 (2023) [5].
5.3 Dynamic Authorisation – OPA + Gatekeeper
OPA can be deployed in either sidecar or centralised mode. For Kubernetes environments, the Gatekeeper project enables policy synchronisation with data plane access control (CRD ConstraintTemplate).
- Example of a sensitivity policy:
package observability.sensitivity

  # Niveau 0 = public, 1 = interne, 2 = confidentiel, 3 = secret
  sensitivity[span] {
      span.attributes["http.url"] == "/login"
      span.sensitivity := 3
  }
5.4 Encryption and immutable storage
- TLS 1.3 mandatory between all points (agent → proxy → collector).
- Encryption at rest using keys managed by a KMS (e.g., AWS KMS, HashiCorp Vault).
- Immutable storage – Enable the “Object Lock” feature on the S3 bucket where audit logs are exported.
5.5 Observability of observability
Paradoxically, the Zero-Trust pipeline must be monitored: OPA metrics (opa_decision_duration_seconds), refusal rates (trace_access_denied_total), and anomaly alerts (a refusal spike > 5% indicates a possible service compromise).
5.6 CI/CD and automation
Integrate policy validation into GitOps pipelines: every modification to the Rego file triggers an integrity test (opa eval) prior to deployment.
6. Use Case – Multi-cloud payment platform in 2025
6.1 Business context
A European fintech operates a payment platform distributed across AWS EU‑West‑1, Azure France Central and an on-premise data centre for local compliance. Services include:
- frontend-web (React) – card data collection.
- payment-gateway (Go) – debit orchestration, card network calls.
- fraud‑engine (Python) – real-time scoring via ML model.
Traces contain masked PANs, authentication tokens and risk scores: highly sensitive data.
6.2 Zero‑Trust Implementation
| Step | Action |
|---|---|
| Identity | Each pod receives a SPIFFE ID via SPIRE (e.g. spiffe://fintech/ns/payment-gateway/pod-123). |
| Sensitivity | The payment-gateway spans are annotated trace.sensitivity=3. The fraud-engine adds sensitivity=2. |
| OPA Policies | - Only services within the same domain (fintech) may read traces with a sensitivity level ≥ 2. - Audit teams (group audit-team) have read access to all sensitivity levels, but exclusively via the dedicated dashboard. |
| Proxy & Collector | Istio sidecar with mutual TLS; OPA integrated via Envoy filter (ext_authz). |
| Audit | Every access decision is stored in an S3 bucket locked for 30 days (Object Lock). |
6.3 Observed Results
- 22% reduction in mean time to detect fraud due to immediate trace access by the fraud-engine, bypassing ops teams.
- GDPR compliance ensured: audit logs demonstrate who accessed which traces, featuring certified timestamps.
- Minimal operational impact – additional latency induced by OPA was < 2ms (measured via opa_decision_duration_seconds).
This scenario demonstrates that Zero-Trust observability can be deployed within a highly regulated context without sacrificing performance.
7. Expected Benefits and Success Indicators
| Benefit | Underlying Mechanism | Recommended KPI |
|---|---|---|
| Enhanced Security | Contextual authorisation, granular encryption | % of legitimate trace requests denied (false positive rate); number of incidents related to trace access. |
| Regulatory Compliance | Immutable audit trail of access decisions | Number of successful audits without findings; average time to generate the access report (audit_report_time). |
| Operational Visibility | Real-time trace accessibility for authorised services | Average trace transmission latency (ms); collector availability rate. |
| Reduction in response costs | Early detection through controlled access | Mean Time to Resolution (MTTR) before/after implementation. |
| DevOps agility | Decoupling of monitoring and data access | Number of support tickets related to access rights (decrease). |
These indicators enable CIOs, CISOs, and product teams to measure the added value of Zero-Trust observability.
8. Limitations, risks and points of vigilance
8.1 Increased complexity
Adding a dynamic authorisation engine increases the control plane: policies, SPIFFE certificates and OPA configuration synchronisation must be managed. Incorrect parameterisation can lead to legitimate denials (impacting debugging).
8.2 Critical path performance
Although measurements show latency < 2ms, in ultra-low latency environments (e.g., high-frequency trading), every millisecond counts. Delay tolerance must be evaluated before enabling control across all flows.